How to Build a Modern Data Warehouse
Why Data Quality Is Essential for Modern Business
Turning Data into Drive: Faster NetSuite Insights for Multi-Channel Retailers
Powering-up Your Cash Planning Process with Machine Learning
Are you getting the most out of your Qlik Sense monitoring tools?
One of the first things I do at the beginning of the month is review the activity in the monitoring applications. We use Qlik everyday to analyze data that drives strategic decision making, so it only makes sense to take that same approach to understanding how Qlik is being utilized within our environment. In order to do this, we take a quick look at a few key elements of those monitoring tools.
For our clients that have NPrinting, we’ve developed a standard report that shows those key elements of the operations monitor and the license monitor for the past month. For those that don’t, we have created additional views in the monitoring applications to do the same.
First up is a quick glance at the engine CPU and engine RAM monitoring for the past month to be aware of any spikes to these two graphs. We can quickly investigate any significant or consistent spikes across the previous month leading us to important questions about our environment: Do we have a cluttered reload process? Is there a problematic app causing spikes in the CPU or RAM? Are there users causing issues with a private sheet?
The next item to consider is a review of the most active applications in the environment by tracking sessions in the last month. Usually, I split this out to look at the last 14 days, 21 days, month and 90 days. By analyzing this you can quickly spot any trends in the applications usage while also understanding which applications are getting the most attention in your environment. With this information, you find timely answers to important questions about how your applications are being utilized.
Understanding application usage can be furthered in more recent versions of Qlik Sense by analyzing sheet usage. Monitoring sheet activity can help you consolidate large apps if needed or begin an investigation into why sheets are being underutilized: Are those sheets delivering accurate results? Is more detail needed? Do users understand the visualization created?
We also want to review user session activity. By monitoring this you can quickly understand which users are utilizing their Qlik access and which are not. Understanding your most active users can identify internal champions to drive collaboration and more advanced development. Monitoring your inactive users can raise essential questions around how to drive engagement from allocated users who have no recent or very limited activity. Are these users getting the information they need? Is training required for the users to better understand their dashboards? Can these allocated licenses be put to better use elsewhere?
With the above considerations, we can leverage the monitoring tools to answer questions about our environment, but more importantly, we can leverage these tools to drive engagement of our users towards our most critical applications and get the most out of your Qlik environment.
Qlik OpenAI Connector: 3 Essential Benefits
Qlik’s OpenAI connector is a powerful tool that allows you to leverage the capabilities of OpenAI’s natural language models within your Qlik apps.
What is the Qlik OpenAI Connector?
The Qlik OpenAI Connector is a Qlik Sense extension that enables you to send prompts to OpenAI’s natural language models and receive responses in your Qlik apps. You can use the connector in various ways, such as:
- In chart expressions, to generate natural language insights or explanations based on your data
- In the data model, to enrich your data with additional information or analysis from OpenAI
- In application automation, to automate tasks or workflows that involve natural language processing or generation
How does the Qlik OpenAI Connector work?
To use the Qlik OpenAI Connector, you need to have an account at platform.openai.com and pay a fee based on the computing resources you use. However, there is a free trial available. You will find the connector under “analytics sources” when creating a new data connection.
With the connector, you can create prompts using variables, fields, or expressions from your Qlik app. A prompt is a text input that tells OpenAI what kind of response you want. For example, you can ask OpenAI to write a summary, suggest a reply, generate a question, or complete a sentence.
You can select different models to send your prompts depending on your use case. OpenAI offers several models with different capabilities and trade-offs, such as:
Davinci: The most advanced and versatile model, capable of generating high-quality and diverse responses for any prompt
Curie: A smaller and faster model than Davinci, suitable for tasks that require less creativity or complexity
Babbage: A specialized model for numerical or tabular data analysis
Ada: The smallest and cheapest model, suitable for simple tasks that require factual or straightforward responses
You can also customize other parameters of your prompts, such as:
Temperature: How creative or diverse the responses are. A higher temperature means more randomness and variety, while a lower temperature means more predictability and consistency.
Max tokens: The maximum number of tokens (words or symbols) the model can generate as a response. A higher max tokens means a longer response, while a lower max tokens means a shorter response.
Top P: The probability threshold for selecting the next token. The model will only consider the tokens with a cumulative probability of less than or equal to the top P value. A higher top P means more diversity and exploration, while a lower top P means more confidence.
Frequency penalty: How much the model avoids repeating words or phrases. A higher frequency penalty means less repetition and redundancy, while a lower frequency penalty means more repetition and emphasis.
Presence penalty: How much the model prefers using new words or phrases. A higher presence penalty means more novelty and diversity, while a lower presence penalty means more familiarity and similarity.
What are some use cases for the Qlik OpenAI Connector?
The Qlik OpenAI Connector opens a world of possibilities for using natural language in your Qlik apps. Here are some examples of how you can use it.
Summarizing public sentiment toward a product or company
You can use the connector to analyze social media posts, reviews, or feedback about a product or company and generate a summary of the main themes or sentiments. For example, you can send a prompt like “Write a summary about the reception towards ” & [Product] & ” by ” & [Company] and get a response like:
“The reception towards Product X by Company Y is mostly positive, with customers praising its quality, design, and functionality. However, some customers have complained about its high price and poor customer service.”
Suggesting responses to customer support tickets
You can use the connector to help your customer support representatives handle tickets faster and more effectively. You can send a prompt like “Suggest a response for a customer support representative for the following case: ” & [ticket_text] and get a tailored response like:
“Dear Customer,
Thank you for contacting us. We are sorry to hear that you are having trouble logging in to your account. We apologize for any inconvenience this may have caused you.
We have fixed the issue, and you should be able to log in now. Please try again and let us know if you still need any help.
Thank you for choosing our service.
Sincerely, Customer Support Team”
You can then use application automation to send this suggestion to a Teams channel or an email address.
Generating social media posts from job descriptions
You can help your Marketing department by generating social media posts. You can send a prompt like: “Write a LinkedIn post for the following job description: “ & [raw_job_description] and get a response like:
“📢 Are you a junior/mid-level BI consultant looking for an exciting opportunity? 🤔 Pomerol Partners is hiring! 🎉 We are looking for someone with a degree in Computer Science or equivalent, 2-3 years of Software Engineering experience, knowledge/experience with Microsoft Power BI, ETL processes and Data Modelling, Data Bases (Postgres, SQL Server, Oracle) and SQL. You should have functional knowledge on reporting and data analysis, an analytical mind with a problem-solving aptitude, self-motivation and commitment to deadlines, be a team player and have good verbal and written English communications skills. 🌍 You will participate in technologically attractive and international projects; receive training and certifications; enjoy hybrid work; and be integrated into a young, solid, ambitious and motivated team. 🤝 Send us your CV in English! #PomerolPartners #BIConsultant #JobOpportunity #DataAnalysis #ProblemSolving #TeamPlayer #HybridWork”
You can do this in the data model to store responses and create a results library.
These are just some ways you can use the Qlik OpenAI Connector to enhance your data analysis and communication. Don’t hesitate to get in touch with us if you want to learn more about this connector or see it in action.
We hope you enjoy using the Qlik OpenAI Connector and discover new insights and opportunities with OpenAI’s natural language models.
3 Steps to Build a Successful Self-Service BI Project
Our appetite for information at work is thriving and the companies that can adapt their culture and attitude to information and analytics will be able to service this demand and see a competitive advantage over their peers who are two steps behind.
In this age of information overload, we’ve become accustomed to having the answers to all our questions at our fingertips, so building a self-service business intelligence is a necessity. This tide change in our expectations is naturally flowing over into the workplace. Our appetite for information at work is thriving and continues to grow. Additionally, the companies that can adapt their culture to information will be able to service this demand. This will allow them to have a competitive advantage over their peers who are two steps behind.
Enabling your workforce with the information they need to make better business decisions is a win-win, and in today’s business environment that means building a self-service analytics platform. But what’s the secret recipe? Successful business intelligence (BI) and analytics projects have similar characteristics, here are just a few.
1. Who Builds a House Without a Plan?
Establishing a strong self-service strategy is critical for success but is often underappreciated and overlooked. More than just an ‘idea about where you’re heading and who’s going to participate’, it’s a comprehensive plan. The plan maps out the people, resources, and objectives that will drive the project forward and ensure business value is maximized.
Self-service BI projects are often chartering new territory within the organization, so it’s important to maintain an agile and flexible approach so you can deal with the curveballs along the way. However, it’s also critical to recognize that when creating something new and challenging, the norms within an organization being able to communicate a firm plan is more important than ever.
Get the right people together and ensure they have the time to dedicate to the initiative. All too often the project team is a winning mix on paper, but competing responsibilities reduces people’s effectiveness and hinders the impact of the team as a whole.
In addition to this, finding the right executive sponsor for your project is critical as they can become a magnet for resources.
2. Find an Executive Champion to Fly the Flag
Finding an executive sponsor is pivotal to creating a successful self-service business intelligence project for several reasons. Vision, experience, and sway within the organization are all important, but so is the ability for a senior leader to create drive and accountability amongst the data project team.
An executive sponsor can help guide change with their wider enterprise perspective, identifying potential bottlenecks or conflicts in advance that may not be seen by other team members. Naturally, the executive is in a better position to eliminate these roadblocks and ensure the path to success is clear.
The modern BI project will often challenge traditional IT policy and workflows. Therefore, having an executive on board to help justify and facilitate your demands for change makes a significant difference.
3. IT and the Business Should be Buddies
Traditionally, IT was the gatekeeper to all things data. They would prepare, analyze, and then report to the business. However, this left many unanswered questions and with no ability to dig deeper and the value generated by this style of reporting was limited.
Moving forward to the first versions of self-service, companies tried to reduce the hoops to jump through by providing curated cuts of data to business functions to build their own reporting. This was a step in the right direction but brought with it other issues. Some of the issues included inconsistency in views for different business units and a lack of visibility into the logic that created those views.
Come 2022, the modern analysis environment sees IT and the business working in partnership. While still having the overarching responsibility of governance and security, IT’s role is to empower the business and achieve the strategic goals defined at the top table.
A modern approach to analytics combined with the latest tools means security and governance don’t have to be compromised in a direct trade-off to innovation and progress. Modern self-service business intelligence tools have governance baked in. In many cases the business can be self-sustainable once IT has laid the ground rules. Instead of throttling back the torrent of data, IT can set up guard rails to help navigate and direct the users to success.
From Data Capture to Analytics–The Game is Changing Fast!
The last ten years has seen our ability to capture and record information grow exponentially. On the contrast, the cost of doing so has plummeted. Companies have raced to prop up storage with traditional databases growing into the ‘data lake’. In many cases, it is an understatement as the data lake has grown into an uncharted ocean. Generating value from this ocean of data and empowering users to take advantage of is the hurdle most companies see before them.
A robust self-service platform channeling useful information to the front line will become the standard within organizations. New and innovative tools tackling data pipelines, NoSQL storage, and machine learning are also bursting onto the scene. Therefore, we need solid BI platforms with sound foundations to bolt on to. Data literacy is on the rise and the appetite is there, so time to roll up the sleeves. What more could you want than a hungry customer?
5 Strategies for Creating a Powerful Data Department
Effective data teams will be tasked with creating a program that not only measures success but also inspires employees to take ownership of the outcomes.
Introduction
Data can be immensely powerful for companies looking to use technology to improve their performance, when used correctly. Data specialists can help your organization make more informed decisions with the information you have, improving its efficiency and helping you avoid pitfalls that could prove disastrous for your business. But data science is about much more than just providing recommendations – it’s about creating a culture of data-driven decision making throughout your organization. In this article, we’ll look at how you can use data to inform decisions in your company, why having a data-driven culture is important for success, and how to build one of these cultures at your firm or organization.
What are the benefits of a data-driven culture?
A data-driven culture is a culture where data is used to make decisions, to measure success and inspire employees. While it’s easy to see the benefits of a data-driven culture from an internal perspective, let’s take a look at how it can benefit your customers too:
Using data for decision making allows you to find patterns in customer behavior that would have been hidden otherwise. You’ll be able to understand what motivates them and what doesn’t. This will help you create better products or services that match their needs and aspirations more closely.
Measuring success shows customers they are valued by you because they provide useful information about themselves when they interact with your business or organization. A good example of this is LinkedIn encouraging users who have added connections or liked content on its site over time by showing them posts from those people above others in their news feed; this means its content has been valued highly enough by other users so as not only makes itself visible but also encourages engagement amongst friends/likes/pages which keeps them coming back again and again!
This helps companies highlight key metrics around user activity which helps improve future iterations of product offerings based upon user input.
How to build a data-driven culture
As the data-driven culture is more and more important, the role of the data consultant is becoming increasingly critical. Without a strong team of data scientists to support their business, companies are leaving themselves vulnerable to mistakes that could be easily avoided with the right tools in place.
The first step in building a strong team and building an effective culture is understanding why it’s so critical:
- Data drives decision making
- Data drives business strategy
- Data drives customer experience
Creating an environment where everyone understands the value of data and believes in its ability to drive decision making
To create a culture of data science, you need to teach people why data matters. You can do this by educating them about the importance of data in decision making. Emphasize how important it is to understand the context behind decisions and not rely solely on gut feelings.
You can also allow people to see how powerful your toolset is by showing them its capabilities through demos, workshops, and other interactive sessions. If you’re working with a smaller team that might not be able to attend these events (or if they aren’t available), make sure each member has access to all the resources they need online so they are able to keep up with their colleagues who are learning on-the-go.
Deciding on metrics
Once you’ve defined your goals and objectives, it’s time to identify the metrics that will help you achieve those goals. You want to make sure the metrics you choose are quantitative and measurable. In other words, they should be focused on outcomes rather than processes—for example: “We want to increase sales” versus “We want to increase inventory turnover.” They also need to be easy for everyone in your organization (not just data scientists) to understand; otherwise, they won’t have much value as a tool for communication or accountability. Furthermore, they must be easy for anyone in the company (including executives) who needs data-driven decision making tools at their fingertips—i.e., they need not require special training or knowledge of statistics in order for someone else within an organization’s hierarchy chain of command
How to use your metrics to make decisions
You’re probably familiar with metrics. They are a set of quantifiable numbers that provide useful information about your business. Metrics can help you understand what’s working, what isn’t, and how to fix it. You should definitely start using them!
That said, not all metrics are created equal; some are better than others at providing actionable insights into your business. Let’s take a look at two types of metrics that we recommend for data-driven decision making:
- Key performance indicators (KPIs) – KPIs show progress from the past few months or quarters toward a specific goal (for example, sales). They’re easy to access and track continuously throughout the year because they’re often delivered in charts or graphs on dashboards that display historical trends over time. Additionally, they’ve been well researched by both academics and professionals alike so we know which ones work best when used together within certain contexts (for example marketing vs customer service).
- Performance indicators – Performance indicators tell us how well we’re doing in specific areas but don’t give us much context as far as whether our efforts have been successful thus far—which makes them more difficult for decision makers since no actionable insights come from them unless there’s already been enough time invested into analyzing results first! However these can be very valuable when determining whether things need tweaking later down the line since many businesses tend towards perfectionism instead of experimentation (due largely because their “experiments” aren’t always considered successful before trying something else new again). These types include financial measures like ROI which show how much money was spent versus how much money was made during a given period/time frame etcetera.”
Where data is priority number one, the most important trait is trust
In any relationship, trust is an essential ingredient. It’s how people feel that you have their best interests at heart, and it’s what keeps them coming back for more. In a data-driven culture, trust is of the utmost importance—especially when your coworkers are all working on different projects and never actually meet face-to-face.
The key to building trust in this environment is transparency: if everyone knows what everyone else is doing, they can trust that everyone is working toward the same goals. For example: if one team member finds some new insight while conducting research on their own time, they should share it with the rest of their company so everyone can use it going forward (and maybe even incorporate it into their own work). Allowing employees this freedom creates a sense of ownership within each person’s role; they feel like they’re part of something bigger than themselves because they’re contributing toward something larger than themselves—which builds camaraderie among employees as well as brand loyalty among customers or clients who value such things!
Effective data teams will be tasked with creating a program that not only measures success but also inspires employees to take ownership of the outcomes.
To ensure that your data program is successful, you must also create a culture of data-driven decision making. This means that employees should be able to use data to make decisions and not just rely on the opinions of their managers or personal experience. It’s also important for your team members to understand how their work impacts the overall goals of the company.
When it comes to measuring success, effective teams will set goals and create programs with actionable metrics in mind. For example, if you have an email marketing campaign that you want people to sign up for (which would then lead them into becoming customers), then it would be important for your team members to know what percentage of recipients actually sign up after receiving an email from you instead of just sending emails blindly hoping something good happens.
Conclusion
To effectively create a data-driven culture, you must ensure that everyone understands and believes in the value of data. Trust should be at the core of your organization – if it is not present then you cannot hope to successfully implement a data program with success. Companies need to decide how they will use their metrics in order to make decisions about future actions – but always remember that these decisions should still be based on gut instincts as well as data analysis. Just like any other tool, there are limitations to what information can tell us about our world around us so never stop thinking for yourself!
Discover and Solve Business Intelligence Collaboration Challenges
The Problem
So here’s the problem. How do you foster sharing and collaboration between users of your analytics platform? How do you transform ‘Consumers’ of analytics to ‘Contributors’? The data flow shouldn’t be a one-way street, and we shouldn’t be consuming the final output in silos. It turns out this is partly a working culture challenge, breaking down our ‘old way’ of working can be difficult, but there’s also a lack of ‘in-app communication’ within most BI tools. How can we expect workers to drive value from the information we’re providing if we’re not giving them an effective way to communicate and share insights?
Business Intelligence is Changing……..Fast!
The demand for data, how we’re filling those data requests and who’s doing it is undergoing a massive transition. ‘First Generation’ BI was centrally controlled and delivered by IT, while ‘Second Generation’ BI saw small analytic groups within business functions querying data sources and building their own reporting. ‘Third Generation’ business intelligence is a new beast based on ‘democratization of data’, but what does this really mean? Well, we’re starting to rethink the custodianship/stewardship/ownership roles around our business data. There’s often a tug-of-war going on between I.T and ‘The Business’. One core objective of ‘self service BI’ is to reach a new audience. It’s about delivering data and insights to the far reaches of the organization in a timely, structured and governed way. The potential impact to improve business operations is immense……..when we get it right.
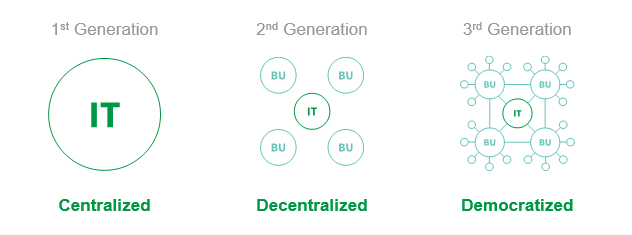
But democratization of data creates a new challenge…..
How does this broad and disparate user base, sometimes at the periphery of the organization, communicate with each other? Picture a sales rep on the road, a utilities maintenance worker out in the field, or a nurse working the ward. How do they raise data quality issues, share insights with peers, record comments and chat about what they’re discovering? It’s a common thread I’ve seen in all self-service BI environments. Users are taking screen shots, exporting data back out to excel, emailing each other, copying and pasting URLs and setting up teams in external messaging platforms. The missing link here is ‘in-app communication’……and thanks to ‘VizLib Collaboration’, we have a nifty solution for Qlik – and boy have they hit the mark.
VizLib’s extension for Qlik Sense appears as either a popup or embedded chat window within a Qlik Sense app. Users of the app can chat in real time with all the bells and whistles we’ve come to expect from a modern messaging app. Even gifs and emojis for those who have left text communication behind!
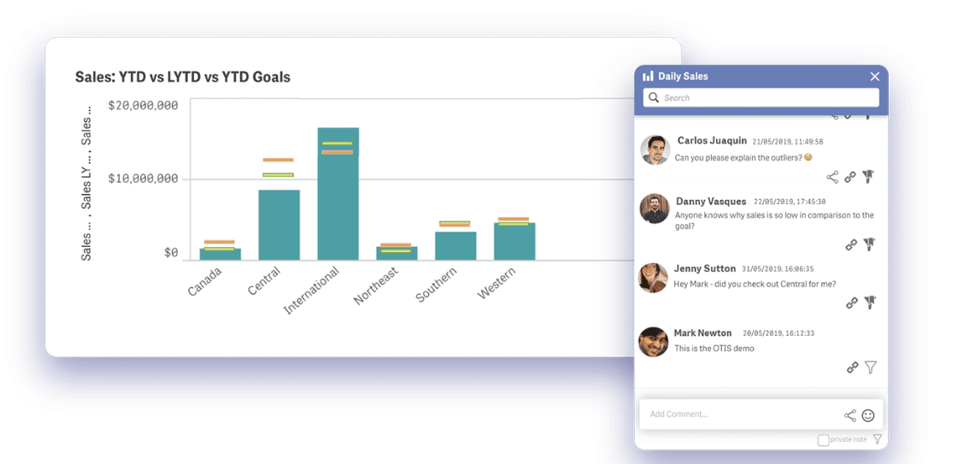
Comments can be associated with an individual chart or the entire sheet, and you can comment to the whole user group, or send as a private note. To add context to your comments, bookmarks or current selections can be included so that others can easily recreate on their end the scenario you’re seeing. There’s Slack and MS Teams integration, and the extension will even auto-generate an email with screenshots, the underlying data as an attachment, and a hyperlink for the recipient to navigate directly back to the app in question.

Collaborate and discuss insights in the same place you discovered them!
No more editing screenshots in MS Paint, no more emailing urls, no more explaining what filters you’ve applied in hope that your colleague can recreate your scenario on their end.
Qlik has always been ahead of the game in the self-service BI department, and this innovative new extension by VizLib is the catalyst that can really empower self service analytics from the organization’s core right out to the furthest edges.
Contact Pomerol to see how your analytics consumers can become contributors!
Smart Chicken’s Inspiring Success: Leading the Way in BI and Analytics
Tecumseh Poultry was founded in 1998 based on a simple goal, “to produce the best fresh chicken in the United States”, and that’s what they do! Over 20 years they have defined and then implemented methods which result in the highest quality finished products. In other words, they do things the right way. Not necessarily the easiest, fastest or most efficient way. Simply the right way.
So, what exactly does this mean? Proper treatment and care of their chickens and people, and the utmost care and discretion in how they process and package their product. Furthermore, they do all this while keeping a careful eye on the environment and on the sustainability and renewability of the resources they rely on.
Beyond being industry innovators in their day to day operations, they’re also 10 steps ahead when it comes to how they analyze their business and are visionary in how they use data to identify opportunity for improvement. In fact, Smart Chicken has more advanced predictive analytics than many investment banks we’ve worked with. Recognizing this vision early on, Pomerol was very excited to be given the opportunity to help Smart Chicken take their BI and analytics to the next level.
“Smart Chicken has more advanced predictive analytics than many investment banks”
No shortage of business challenges….
There are many challenges unique to producing a perishable fresh product. The shelf life is short, high wastage would make the business model unfeasible, and there’s no real opportunity for inventory. So, supply and demand need to be in sync, and this requires precision planning and a perfect understanding of your market. Supply is relatively fixed in the short term, but demand can fluctuate wildly depending on time of year, weather and promotional activities. Believe it or not, demand for white breast meat skyrockets for the short period of time that our new year’s resolutions are still intact, before settling back down in February. Try planning around that!
Beyond this, there are a raft of challenges unique to poultry production. Football season sees a huge uptick in wings consumption, but last time we checked, a chicken only has two wings, so there’s no ability to increase production of this single SKU. In another twist, Thanksgiving and Christmas is a time of year where we all get together and eat whole Turkey, but that sees the demand for whole chickens plummet for November and December. Planning around these erratic peaks and troughs causes plenty of pain, but together with the Smart Chicken team we’ve developed some novel ways of optimizing the planning process through a combination of live analytics in Qlik dashboards, and machine learning assisted forecasting with Data Robot.
Using Qlik to shed light on the business
The power of Qlik is leveraged for both its ETL capabilities and as a data visualization and reporting platform. Powerful associative models consolidate data from ERP, CRM, live production and planning tools giving managers an asset to empower decision making.
The customer demand forecasting process is a critical step in the chain to running a successful operation. Visualizing the forecast in Qlik, managers can quickly move from a brand level right down to individual SKUs. Different ordering patterns unique to geographies are easy to see, and the demand fluctuations driven by weather, events, promotions and holidays are all evident when trended or exposed through geographic maps.
Qlik provides a great view into the forecasting and sales data, but with such diverse ordering patterns there’s real opportunity in perfecting the forecasting process right down to the SKU and customer level. Smart Chicken and Pomerol enlisted the help of Data Robot to apply Automated Machine Learning technology to the demand forecasting process.
Taking forecasting to the next level with Data Robot and Automated Machine Learning
What really separates Smart Chicken apart from their competitors is how tight their forecasting and planning process is. Representatives in the field have their finger on the pulse by chatting to customers in supermarkets and they feed anecdotal information back into the planning team, while back at head office demand is forecast right down to the SKU and customer level, something most companies would not dare attempt.
Instead of applying a single forecasting algorithm across all customers and SKUs, Data Robot has enabled Smart Chicken to mathematically cluster and segment similar customers and products based on volume and ordering behaviors. Unique forecasting models are then auto-generated for each unique cluster.
Pulling from a library of hundreds of predictive models, Data Robot ranks its recommended models based on performance, error and speed, and then recommends a model to be put into production. Without an in-house data science team, Smart Chicken uses the power of automated machine learning and predictive analytics to further refine customer demand forecasting.
Beyond demand forecasting
While customer demand is a pivotal data point for Smart Chicken, there are other parts of the business that can also benefit from the power of Data Robot. Predicting the growth trajectory and final weight of chickens can inform the planning process of anticipated supply. In a sector where inventory is almost non-existent, having a keen eye on supply avoids surprises and lets the customer support team know exactly how much produce they have available to distribute. Having advance notice of any expected shortfalls lets customer service pro-actively manage expectations.
In another industry first, Smart Chicken have installed a full end-to-end ‘air chill’ system – the only one of its kind in the US. While the impact this has on product quality is beyond measure, it’s a tricky piece of equipment to run and presents a risk should it fail. Smart Chicken are looking to Data Robot for predictive maintenance. By analyzing the events leading up to previous parts failures, we can begin to predict when another failure is looking likely. IOT sensors constantly measure conveyor belt motor amperage, temperature and tension. The most minute change in tension may indicate a stressed or worn ball-bearing, or a slight increase in motor temperature might indicate an increased level of strain. Being able to pro-actively identify issues before they fail during production hours can have a massive impact on continuity of supply.
Looking to the future
As consumers place a higher importance on the quality and origin of their produce, the market for Smart Chicken’s products is on the rise. The game-changing innovator from small-town Nebraska is setting the bar for the larger producers. We’re excited to be on the analytics journey with them!
Visit the Smart Chicken website: https://www.smartchicken.com
Transforming Pharmaceutical Sales with Data Visualization
Data Analytics in Hospitality
Transforming Airport Operations with Advanced Data Warehousing
Pricing Intelligence in Banking
Rehypothecation Gap Analysis
Industrial Supply Chain & Procurement
Customer Insight and Marketing Effectiveness
Efficient Data for Shotshell Reloader Production
Building a Data Management & Analytics Strategy
Power Maximizing Snowflake Performance for BI Products

The business world is rushing as technology and innovation enter different areas. Any organization that wants to remain competitive and stand out to customers must make real-time decisions. Of course, these decisions must be supported by the judgment of business experts and backed by data.
If our experts and managers can access relevant and up-to-date information using a data strategy, it can yield incredible results for growing the business. This is where business intelligence has its first impact, managing to describe the causes and results of current actions, as well as providing options to take different paths in the near future. It considers historical data while making predictions or simply analyzing trends.
Every data strategy, from a technical perspective, involves different components, starting with the sources of information and the ingestion of these data from transactional systems into a data repository or data warehouse with analytical features. Once the data is stored in the data warehouse, the data cleansing, transformation, and enrichment processes come. Then, it is followed by correct data modeling so final users can use their visualization tools to display dashboards with strategic information, KPIs, and trends. That provides inputs to decision-making. Data governance processes and business objectives must accompany all these technical elements. If one part does not complement the other, the data strategy would be incomplete and inefficient.
The technical heart of the data strategy is the data warehouse. So, let’s take some time to expand on the concepts related to this and its optimization to optimize the queries that business intelligence analysts perform.
A data warehouse (DW or DWH), also known as an enterprise data warehouse (EDW), is a system for reporting and analyzing structured and semi-structured data from multiple data sources.

This is where our data is located and where we connect our visualization tools. The figure above shows that the data warehouse must have several layers. However, I will not explain in this article the different layers and components that must be included in the data warehouse. I will proceed with the topic of improving performance when consuming data.
To improve the performance of data queries, we must analyze three essential columns:
1. How we have stored our data
2. The human part.
3. The capacity or computing power to process the queries
Storage
Knowing how our data is physically stored and how our database engine retrieves is a starting point for any data project. Remember that in a very general way, we have two prominent types of structured databases: transactional and analytical.
Transactional databases focus on high performance for recurring insertions, changes, or deletions of small transactions, such as points of sale, call centers that contact different clients every minute and need to record data for each one, customer service, inventories, and any CRM and ERP. They are speedy with individual transactions. On the other hand, analytical engines focus on high-performance insertions or data queries of millions of records in minutes or seconds in batch processes. Neither is better than the other. They are focused on different use cases.
Snowflake is currently working on other storage formats to allow transactions; however, we want to analyze its characteristics as an analytical engine.
Physical data storage within Snowflake is based on the concept of micro partitions. A table logically represents data comprising one or more micro partitions. Each micro partition is a group of records ordered either by natural data ingestion or by an established cluster key that allows continuous data reordering according to the fields that make up the cluster key.
Considering this, our first step in optimization is to review the data ingestion processes and validate the order of the records that arrive through files or integrations. If this order corresponds to one of our query keys, we are already on the way to good optimization. If there is no key field to order the ingestion, we have two alternatives: the first and most efficient in terms of the long term would be to modify our processes for creating files that will be ingested into Snowflake. If this is not possible, we have the second alternative, creating a Cluster Key manually to indicate the order the data should have when physically stored.
This solves a use case for querying our data, preferably the most frequently used case. But what about users who query the data using another set of columns as key fields?
One feature of Snowflake is materialized views. You can create different materialized views, each with a distinct cluster key. The magic is that you can query them individually or the original table all the time, and the Snowflake query optimizer recognizes the key structures and clusters of the materialized views. Suppose the service detects that using the materialized view instead of the table is more efficient. In that case, it automatically rewrites the query and retrieves the data using the materialized view. This works with large tables in terms of Terabytes. In small tables, the data will constantly be retrieved directly from the object indicated in the SQL statement since the optimization is null or minimal.
When working on the data structure analysis process, we can identify other objects that can be very useful depending on the specific use case. Sometimes, we can rely on zero-copy cloning to have millisecond copies of the data in a table that we can use for testing or QA. In other cases, we can have dynamic tables in our intermediate layer or our data model layer that do not require customized update processes since they are designed to perform this task through the script that creates them, with the additional advantage over materialized views that they do allow having more than one table as data sources. Here are several links to Snowflake documentation to learn about the different types of objects that will enable you to store data.
Micro-partitions https://docs.snowflake.com/en/user-guide/tables-clustering-micropartitions
Cluster Keys https://docs.snowflake.com/en/user-guide/tables-clustering-keys
Materialized Views https://docs.snowflake.com/en/user-guide/views-materialized
Dynamic Tables https://docs.snowflake.com/en/user-guide/dynamic-tables-best-practices
Zero-Copy cloning https://community.snowflake.com/s/article/Best-Practices-for-Agile-Data-Deployment-using-Snowflake-Cloning-and-Access-Controls
Optimizing storage for performance: https://docs.snowflake.com/en/user-guide/performance-query-storage
Human part
From a human perspective, we will always be involved in some part of the process, whether at the beginning, designing the architecture of the entire process or writing code to carry out the whole data flow.
The first step is crucial: having a design on the general architecture of our solution so as not to go working and resolving issues that could be avoided, as well as thinking about integration with the entire data ecosystem, with other data products and considering all the points to manage the project within a framework that enables data governance. This part is developed by humans, where the experience and knowledge of data platforms and the tools used can provide a competitive advantage and improve implementation time.
Many warehouse implementation projects do not consider the design and architecture part, and although they are not destined to fail, they will have to overcome many challenges, which will increase the time and resources invested.
Another strategic point is the data architecture itself.
The data architecture within the platform must have at least three layers, starting with the RAW layer, also known as the STAGE layer, which covers the raw data ingested from our data sources.
The second layer is where we move our information by performing transformation and cleaning processes. We can combine various data sources and enrich the data. This is part of the ELT paradigm, where the transformations are performed directly in the data warehouse, not in the application that performs the ingestion.
Finally, we have our third layer, where we store the data in a form that tools and end users can consume. This is where we perform the modeling of the different data marts. Whether the data modeling method is Kimball, Data Vault, or another does not matter. The important thing is to have a layer where this activity is developed.
For security purposes, any data visualization or analysis tool and business analysts should connect to this final layer. Data scientists can often connect to the first layers because they need to run different models and experiments. However, any model that wants to be put into production must be connected to the data in the final, consumption, or modeling layers.
Another aspect of performance is the way the code is written. Programmers are used to using cursors; however, in many cases, cursors can be replaced with SQL code using grouping and conditional options. Cursors are effective for performing single transactions; an analytical data warehouse can process millions of records if the query is implemented correctly in a quarter of the time or less than that of a cursor.
Another common practice is including many subqueries levels within a query; this can make the query slow. Subqueries should not have order by.
No functions that transform data should be used in the where statements. Or at least we should avoid using them unless we have no alternative. A straightforward example is that we have a table with 20 million records, and we want to retrieve the records from October 1, 2024. The table has 25 micro partitions to complete the example, and the order_date is part of the cluster key. These two queries work:
Select id, order_date
from tabla1
where ‘2024-10-01’ = TO_VARCHAR(order_date, ‘yyyy-mm-dd’);
Select id, order_date_time
from tabla1
where TO_DATE(‘2024-10-01’) = order_date;
The difference is the response time. In the first example, for all records, 20 million, the date conversion is performed to determine which records should be displayed. The function is executed 20 million times, and the entire table is scanned. The function applied to the column does not allow the use of metadata from the micro partitions or the use of the Snowflake optimizer.
In the second example, the function is executed only once. The converted data is compared with the native value of the column. Additionally, it only scans a part of the table, only the micro partitions that have a date within the minimum and maximum of that column, which could be 5 instead of 25. This second query can take a quarter of the time or less than the first.
We can significantly reduce response time by applying best practices throughout our code.
Compute Power
I have left the processing power part for last because it is the most expensive. However, it is the easiest to configure and scale. For this reason, it is usually the first thing worked on to have short-term results but greatly increasing costs. A good performance analysis and its respective application must contemplate the previous stages first and lastly focus on the processing resource.
Snowflake offers different options. The first and easiest is to increase the size of our virtual warehouse, which comes in sizes XS, S, Medium, Large, and XL up to 6XL. Each size doubles the amount of resources but simultaneously doubles the cost.
If we have complex queries, many transformations, multiple joins, or a large amount of data recovered from a few queries, increasing the size is typically enough. However, having a lot of concurrency, whether it is many simultaneous users or many queries running simultaneously, could not be resolved by increasing the size. In this case, we must work on the multi-clusters instead of the size to opt for better results.
The concept of multi-clustering is to have a minimum number of servers running at a specific size that can increase as there is a demand for resources caused by more users or more queries, up to a maximum number of configured virtual warehouses.
Here, we can apply two types of policies: one that focuses on saving money (economy), where a new cluster is activated only if there are several queues, or the policy that optimizes time (standard), where queries are attended to but if any remain in the queue, a new cluster is activated as quickly as possible.
The number of queries a virtual warehouse can handle concurrently depends on its size and the “MAX_CONCURRENCY_LEVEL” setting. By default, a single-cluster warehouse can handle around eight concurrent queries, as this is the standard value for MAX_CONCURRENCY_LEVEL; larger warehouses can handle more concurrent queries due to increased computing power. Remember that the complexity of each query also affects how many can run concurrently.
The magic of multi-clustering is that you set up a minimum and maximum number of clusters, allowing you to control your budget. Snowflake automatically activates or deactivates them based on the increase in queries during your platform’s peak times of use.
This configuration is simple, but you should take the time to analyze your normal workload and during peak hours to determine the appropriate size and number of clusters required to handle concurrency peaks.
Other services within Snowflake, in combination with the warehouses, include the search optimization service, which allows you to accelerate queries to a table that does not have a specific query pattern. Some users perform queries using the cluster key, but many do not have a pattern. They can search by any column and retrieve small or medium amounts of records with specific queries. This service can significantly improve performance and the time required to return results.
The QAS, or Query Acceleration Service, is an option that you can activate in the warehouse settings. It can improve the speed of query execution by accelerating parts of the query workload and reducing the impact of outlier queries.
By default, it is disabled. Before activating it, it is necessary to analyze the queries that the warehouse regularly processes to take three possible options: the first is that it is not needed to activate it, the second is that the queries that we have in that workload are candidates to improve performance with this service or the third is that we must separate the warehouse into two workloads, that is, into two different warehouses, where one will have the queries that can be improved with this service and the other will resolve all the other types of queries.
Mult-cluster warehouses https://docs.snowflake.com/en/user-guide/warehouses-multicluster
Query Acceleration Service https://docs.snowflake.com/en/user-guide/query-acceleration-service
Search Optimization Service (https://docs.snowflake.com/en/user-guide/search-optimization-service https://docs.snowflake.com/en/user-guide/search-optimization/text-queries )
Optimizing warehouses for performance: https://docs.snowflake.com/en/user-guide/performance-query-warehouse
I hope I have given you an overview of the options Snowflake offers. Each has different impacts and improvements on our performance and, at the same time, our costs. However, an essential point is always that if our users and end customers are happy with the performance and use of our data warehouse, it means that we are moving in the right direction. If this is not the case, it is time to analyze why they are unhappy and whether this is related to our platform not responding in the expected time or because our data products take too long to reach the market.
You can use the official Snowflake documentation to guide you through these processes or contact us. We will happily assess your Snowflake environment and optimize it for performance and costs.
Victor Gomez
Principal Data Consultant
victor.gomez@pomerolpartners.com
Data Driven Decision Making Starts at the Branch
Automating ERP for Complex Pricing
Creating a Unified, Compliant Customer Portfolio
Azure Cost Optimization
MAP Supplier Invoice Reconciliation
Building a Data Management & Analytics Strategy
Findorff is a $900M construction company based in Madison, WI. Their focus is conducting large-scale commercial and residential building projects. Given the change in the economic market, along with their steady growth, Findorff recognized the need to better leverage data and analytics to optimize job profitability, construction forecasting, labor productivity, and marketing & sales opportunities. Following an evaluation process, they decided to leverage the Analytics TO WIN® method to establish a data management and analytics strategy.
The Findorff team followed the Four-Step method and leveraged the pre-built assessments and templates to engage executive leadership, IT leadership and key functions of the business. This ensured the resulting data management and analytics strategy was developed collaboratively, with all three core business stakeholder groups having their needs addressed.
The Decision-Making & Data-Driven Culture assessment was invaluable. It generated much-needed awareness at the executive level about how decisions are made and about the maturity of their data-driven culture. It also provided a structured forum to confirm the corporate objectives, and raised awareness about their strategic data objectives (how is data provisioned, where it is stored, who has access, how it is used in decision-making). The session also helped identify what is needed to enable improvements in how they use data (data quality, availability, retention, etc.). The data and analytics team also took the same assessment and compared their results to the leadership results. This comparison exercise created a no-lose situation – i.e., if aligned, it would expedite next steps… if not, it would help bridge the gap between the data team and leadership to avoid delays. It also made sure that data initiatives were set to support the whole company, and both leadership and departmental leaders were aligned on priorities for maximum impact.
The Findorff team found the Analytics TO WIN® method to be very adaptable, and accommodated the company’s emerging strategic planning process (timing, personnel, input from leadership, IT and all business functions). It eliminated departmental subjectivity/bias via cross-functional consensus, established priorities and prerequisites, balanced load, and drove executive buy-in and approval. It increased confidence in the company’s ability to succeed and became the consistent reference point for measuring progress across all departments in the organization. The result of the Analytics TO WIN® method was a Strategy Matrix that clearly prioritized the most important data management and analytics initiatives. Each initiative was clearly aligned to their data-related strategic objectives, which were aligned to their overall corporate objectives. The data team was
also able to use the Strategy Matrix to prioritize some projects to achieve quick-wins to build early momentum. The Strategy Matrix was presented back to the leadership team on a single page that made it easy for the leadership to understand and approve the first set of key initiatives.
The data team at Findorff is now engaged in executing the prioritized initiatives from the Analytics TO WIN® Strategy Matrix and is already seeing success with the business
© 2022 Total View Analytics
Analytics TO WIN® is a practical and prescriptive method for crafting a data management & analytics strategy. The method includes a series of easy-to-use assessments, tools and templates that help your organization develop a concise and realistic strategy. The resulting strategy serves as the roadmap for your forthcoming data management & analytics-related projects.
What makes the Analytics TO WIN® method so effective?
1. ALIGNMENT – Each of the 4 Steps in the method are intentionally designed to create alignment between the overall corporate or departmental objectives and ultimately, each of the data management & analytics projects in the strategy.
2. STRUCTURE – The method provides a structured approach for crafting the strategy. All too often, strategy projects get “stuck in the weeds” or simply get off-track. The Analytics TO WIN® method avoids these pitfalls by providing the structure to stay focused and complete the process more quickly.